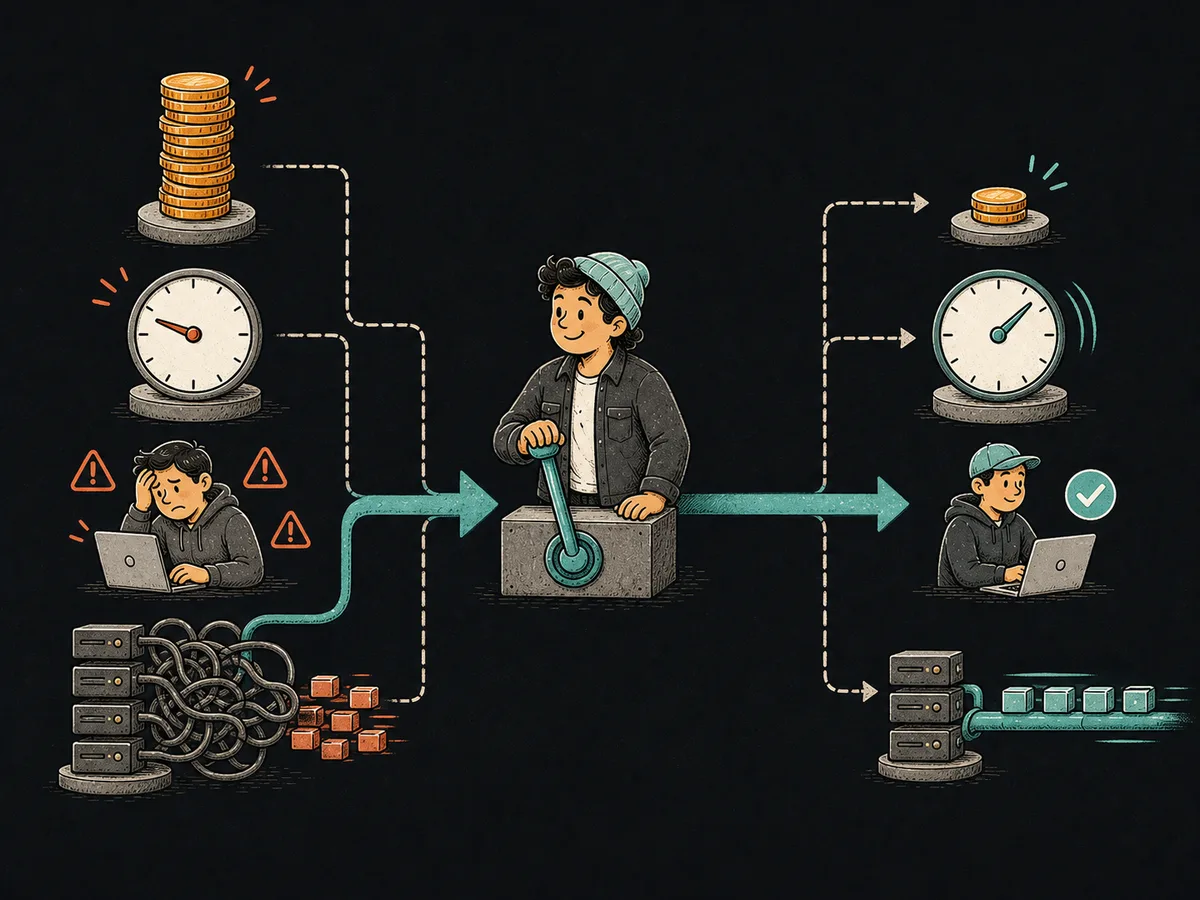
I make production easier to operate.
My backend, DevOps, and site reliability work helps teams recover faster, see what matters, automate risky work, and use cloud resources responsibly.
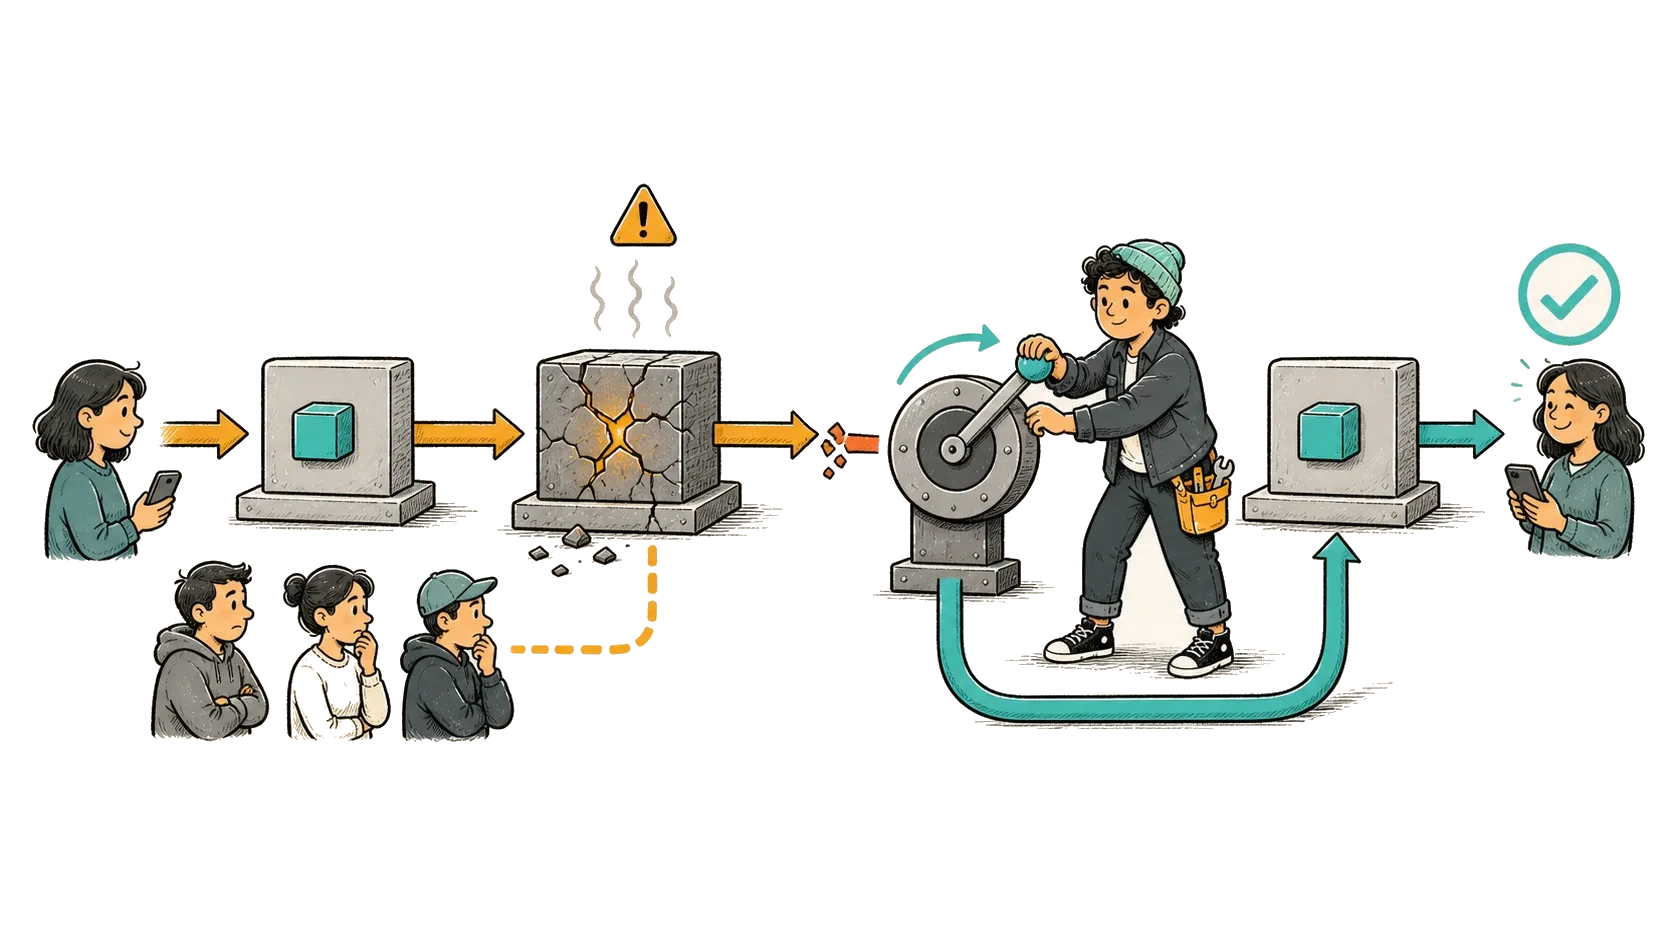
Incident response
Restore service fast, coordinate the response, and turn each incident into a concrete improvement.
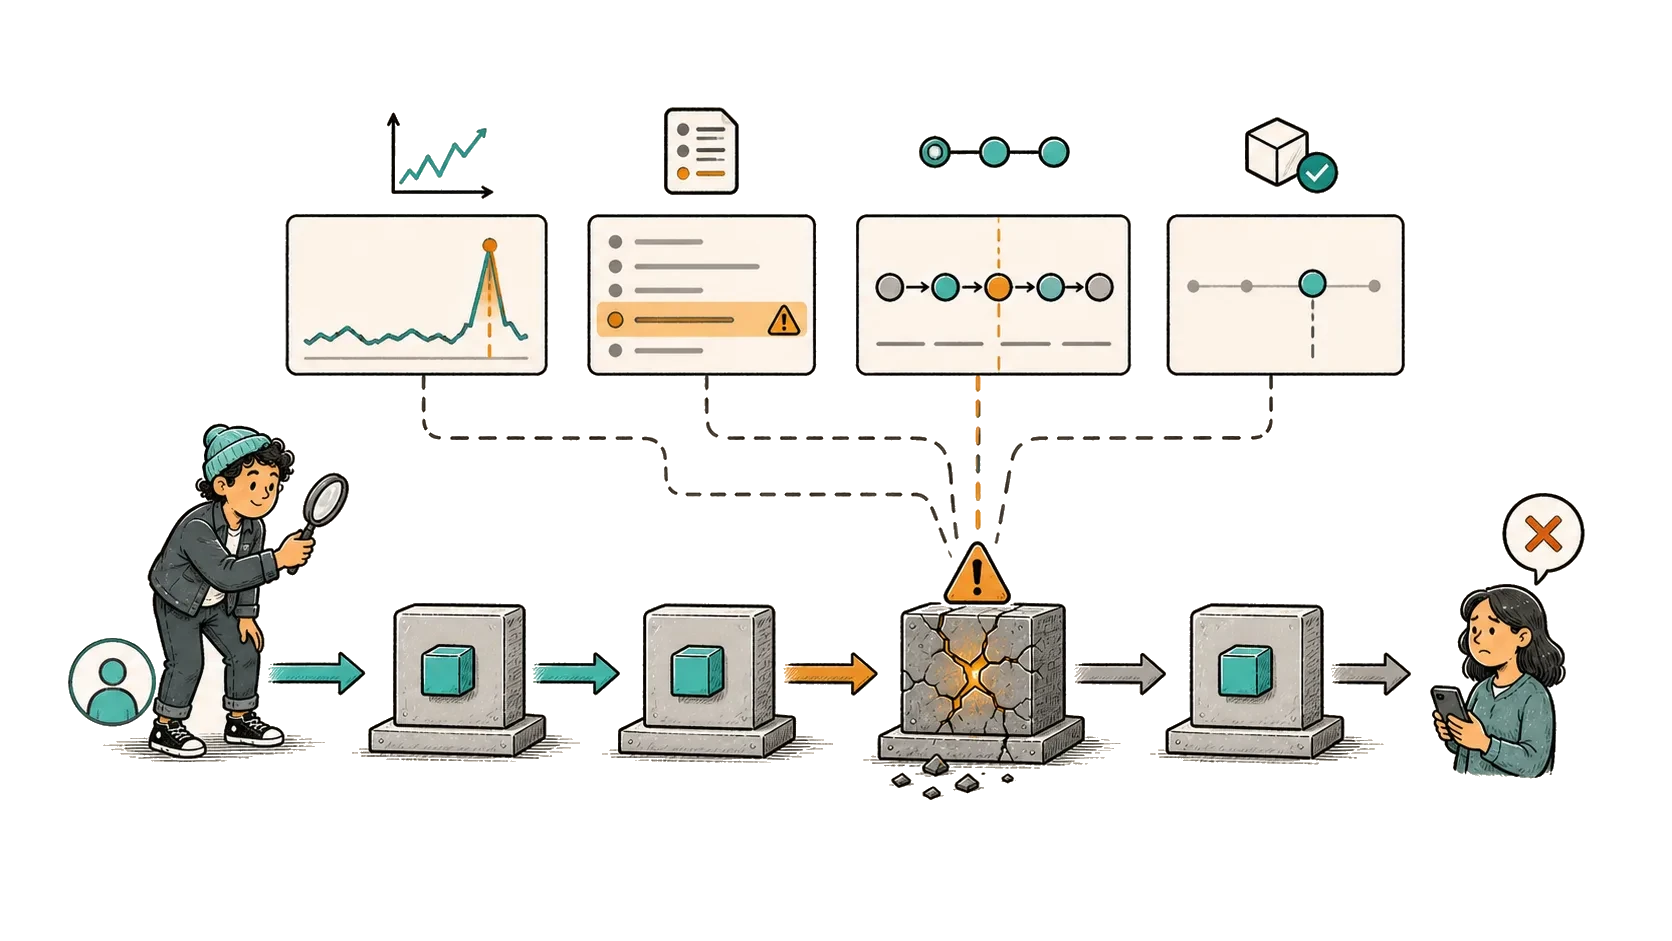
Observability
Use SLOs, metrics, logs, and traces to show user impact without noisy alerts.
Safe automation
Replace repeated manual steps with tested workflows, guardrails, and rollback.
Performance & cost
Reduce latency, resource use, and cloud spend without trading away reliability.
Core stack
- AWS
- Azure
- Docker
- Kubernetes
- Python
- Java
- Quarkus
- Spring
- CI/CD
- Metrics
- Logs
- Traces